

The pricing hit first. On February 4, Mistral AI announced it would transcribe speech at $0.003 per minute—roughly a third of what most enterprise developers pay today. Then came the surprise: a companion model you can download and run on your own hardware, for free.
It's a bold play in a market that has, until recently, belonged to cloud giants. And if the French AI company's accuracy claims hold up, it could force uncomfortable conversations in product meetings from San Francisco to Shenzhen.
Mistral's dual release splits the difference between two competing visions of how voice AI should work. Voxtral Mini Transcribe V2, the cloud service, handles batch transcription with the kind of enterprise features developers expect: speaker diarization, word-level timestamps, support for audio files stretching past three hours. Voxtral Realtime, released under an Apache 2.0 license and already live on Hugging Face, tackles a harder problem—live transcription with latencies under 200 milliseconds. It runs on a single GPU.
That second part matters more than it might seem.
The On-Premise Bet
Speech recognition has mostly lived in the cloud for good reason. The models are large, the compute expensive, and most companies would rather pay per minute than manage infrastructure. But Mistral is wagering that enough developers want—or need—to keep audio processing local.
Consider the constraints: GDPR compliance in Europe, HIPAA requirements for healthcare transcription, bandwidth costs in remote deployments, or simply the economics of transcribing millions of hours annually. At 4 billion parameters, Realtime fits on hardware that startups can afford and enterprises already own. That's small enough to matter.
The architecture uses a sliding-window attention mechanism paired with what Mistral describes as a custom causal audio encoder optimized for streaming. Translation: the model can process audio indefinitely without restarting, a necessity for applications like real-time customer service or live event captioning.
VentureBeat flagged the implications, noting that the 4-billion-parameter footprint opens doors for voice agents and automation systems that larger, cloud-dependent models can't easily reach. Whether that's enough to challenge incumbents remains an open question. But the option to deploy locally, without per-minute fees accumulating, shifts the cost calculus for anyone processing audio at scale.
Two Models, Different Economics
Voxtral Mini Transcribe V2 supports 13 languages—English, Chinese, Hindi, Spanish, Arabic, French, Portuguese, Russian, German, Japanese, Korean, Italian, and Dutch. Mistral claims a word error rate hovering around 4% on the FLEURS benchmark and says the model outperforms GPT-4o mini Transcribe, Gemini 2.5 Flash, Assembly Universal, and Deepgram Nova on accuracy.
Those are the kinds of claims that invite scrutiny. Independent benchmarks will tell the fuller story, but early testing on Hacker News—where the launch drew 945 upvotes and 229 comments—suggested the performance is real, if uneven. Developers posted mostly positive results for real-time transcription, though some flagged accuracy issues on code-switching, particularly French-English mixes.
Speaker diarization works as advertised, labeling who said what with precise timestamps, though the model defaults to transcribing only one speaker when voices overlap. Context biasing, a feature that lets developers feed up to 100 custom words or phrases into each request, addresses a gap that matters more in practice than on benchmarks. Voice agents transcribing medical terminology, customer service bots handling product SKUs, or compliance systems dealing with proper nouns—all benefit from vocabulary tuning. The feature is optimized for English but experimental elsewhere.
Realtime runs under different pressures. Priced at $0.006 per minute via API, it's twice the cost of the batch model, though still cheaper than most competitors. The real value lies in the open weights: download it once, run it anywhere, pay nothing beyond compute.
Latency configurations range from sub-200 milliseconds (aggressive, with a slight accuracy trade-off) to 2.4 seconds (matching batch quality). Mistral recommends a middle ground at 480 milliseconds, where word error rates stay within 1 to 2% of the batch model—fast enough for live subtitling, slow enough to preserve accuracy.
The Enterprise Pitch
Mistral Studio offers an audio playground where developers can test up to 10 files with diarization and timestamps enabled. It accepts the usual suspects: .mp3, .wav, .m4a, .flac, .ogg, with a 1GB file size limit that handles multi-hour recordings without complaint.
The company is specific about competitive positioning. Mistral says Mini Transcribe V2 runs approximately three times faster than ElevenLabs Scribe v2 while matching quality at one-fifth the cost. Benchmarks on Hugging Face break down performance across TEDLIUM, AMI, Switchboard, CHiME-4, and GigaSpeech datasets, with tables showing WER by delay setting and language.
One notable omission: diarization isn't available in Realtime mode yet. That feature remains exclusive to batch processing, at least for now.
The default maximum length for Realtime sits at roughly 131,072 tokens—over three hours of audio, with each token representing about 80 milliseconds. That's a substantial improvement over the 30-to-40-minute limits Mistral cited in its 2025 Voxtral releases. Whether developers will notice the difference depends on use case, but for applications like all-day meeting transcription or surveillance monitoring, the ceiling matters.
A European Alternative?
WIRED positioned the launch within Mistral's broader European AI strategy, noting that small, open, cost-efficient models running locally present an alternative to cloud-dependent systems from Apple or Google. The 4-billion-parameter footprint makes multilingual conversation and translation feasible on consumer hardware—a direction Mistral appears to be exploring beyond pure transcription.
Perhaps. The company has been methodical about carving out territory where hyperscale cloud providers have less natural advantage: open licensing, local deployment, aggressive pricing. Speech recognition, long dominated by models too large or expensive for most companies to run in-house, fits that profile.
The vLLM Realtime API support helps. Teams already running vLLM can deploy Realtime using a WebSocket protocol that accepts base64-encoded PCM16 audio at 16 kHz mono. It's not seamless—Transformers and Llama.cpp support aren't available yet, though the model card invites community contributions—but it's close enough for early adopters.
What the Market Sees
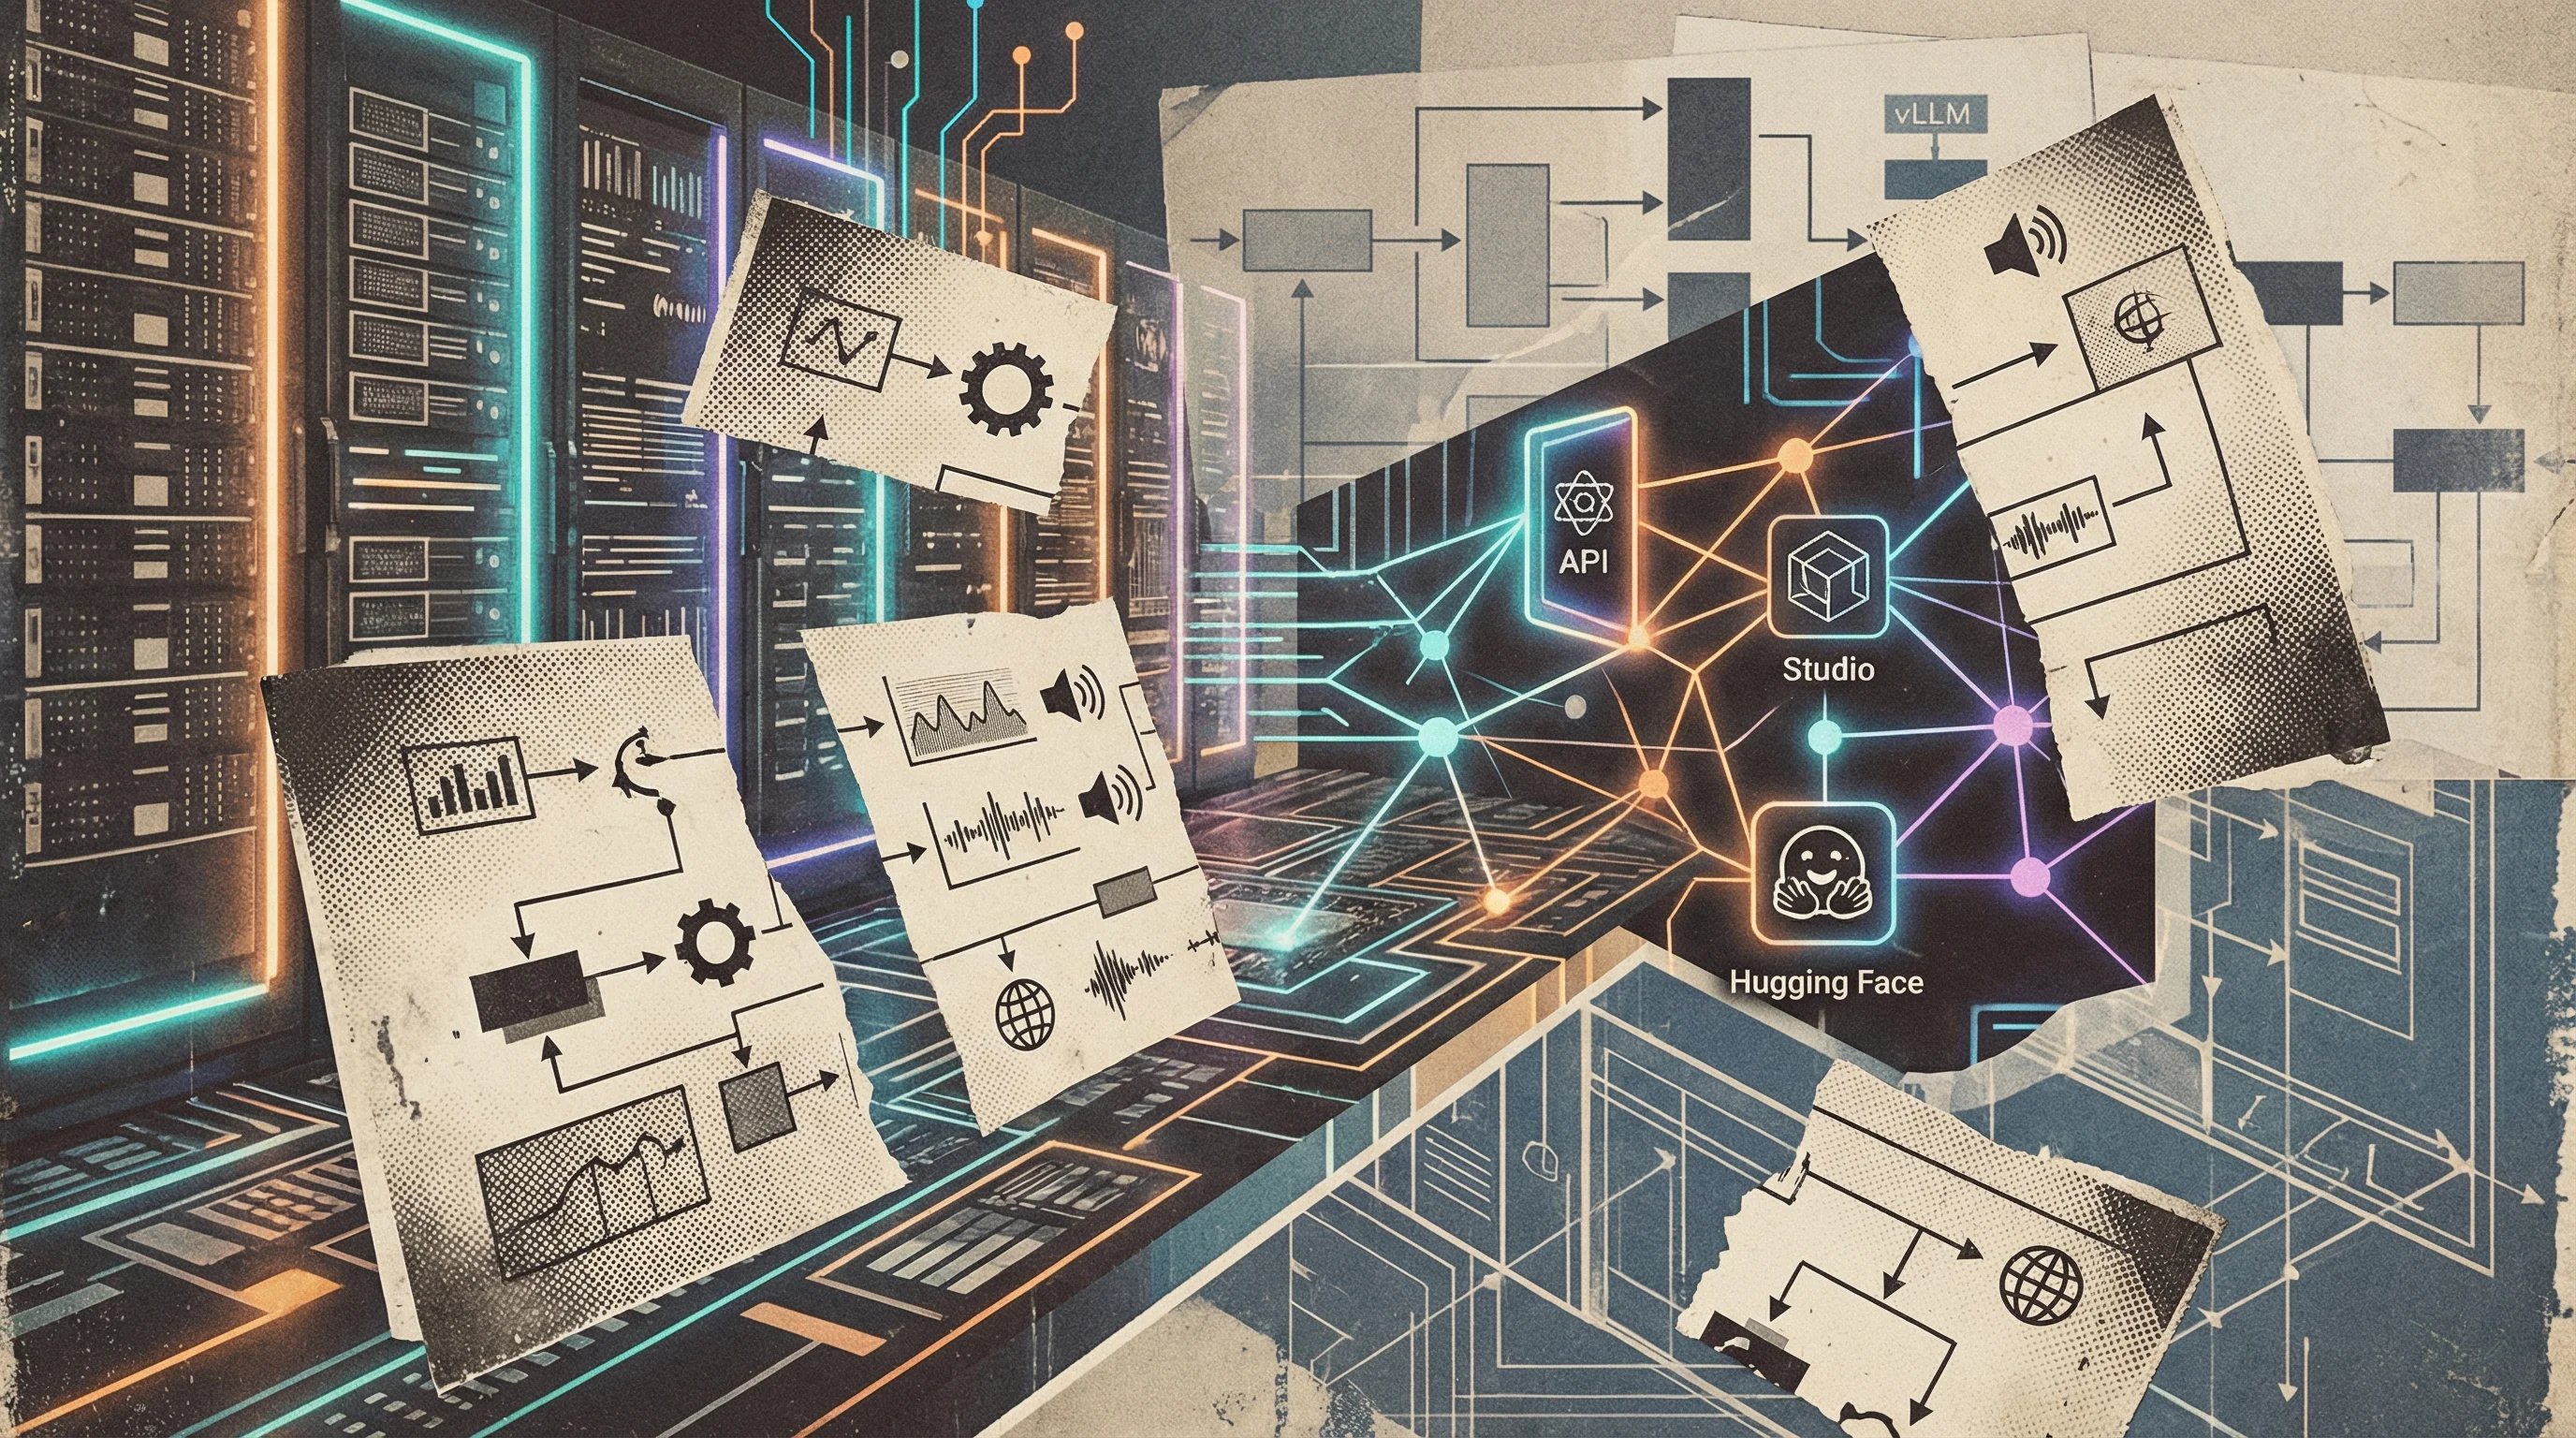
Both models went live February 4. Mini Transcribe V2 is accessible via Mistral's API and Studio. Realtime is available through the API or as open weights on Hugging Face. Documentation covers endpoint parameters (timestamp_granularities, diarize, language override), integration examples, and vLLM serving instructions.
The Apache 2.0 license removes licensing friction for commercial applications—a notable contrast to models with restrictive terms or enterprise-only availability. Mistral targets use cases ranging from meeting intelligence and voice assistants to compliance-sensitive deployments requiring on-premise or private-cloud infrastructure.
At $0.003 per minute, Voxtral Transcribe 2 isn't just competing on price. It's redefining what "cost-effective" means in speech-to-text, particularly when paired with an open-source alternative developers can run wherever regulations, latency, or economics demand it.
Whether that's enough to displace entrenched players remains uncertain. But for a market accustomed to cloud pricing and closed models, Mistral just made the status quo considerably harder to defend.


