

For developers who train language models, the choice has long felt binary: pay cloud providers by the hour or descend into the labyrinth of configuration files and dependency hell. Unsloth, a Y Combinator-backed startup that's quietly built one of the more popular open-source fine-tuning frameworks, is now wagering it can collapse that binary into something simpler—a desktop app experience for training AI on your own machine.
The company released Unsloth Studio on March 17, 2026, a no-code web interface backed by NVIDIA that promises to handle the full training lifecycle locally. The pitch includes performance numbers that tend to matter when you're running algorithms on consumer hardware: twice the training speed, 70% less memory consumption than conventional methods. All without your data ever touching someone else's servers.
Whether it's a watershed or just another tool in an increasingly crowded ecosystem remains an open question.
What You Actually Get
Studio presents itself as a web UI that runs on your own hardware—think of it as accessing something like Notion, except the server is your machine and the models never leave your basement. The platform claims support for over 500 models spanning text, vision, speech synthesis, and embeddings. Models operate through llama.cpp and export to formats that play nicely with vLLM, Ollama, and LM Studio.
The interface includes a chat mode with multi-GPU inference, document handling, and what the company calls "self-healing" tool-calling with integrated search. There's a Model Arena feature for side-by-side comparisons—useful if you're the kind of person who enjoys watching different neural networks spar over the same prompt. Training comes with real-time visibility: loss curves, gradient norms, GPU utilization accessible from any device on your network, assuming you trust your network.
Everything runs locally, or so the architecture claims. Data doesn't leave unless you deliberately share it. Authentication relies on tokens, passwords, or JWT. The system collects minimal hardware telemetry, ostensibly for compatibility.
The Data Workflow Angle
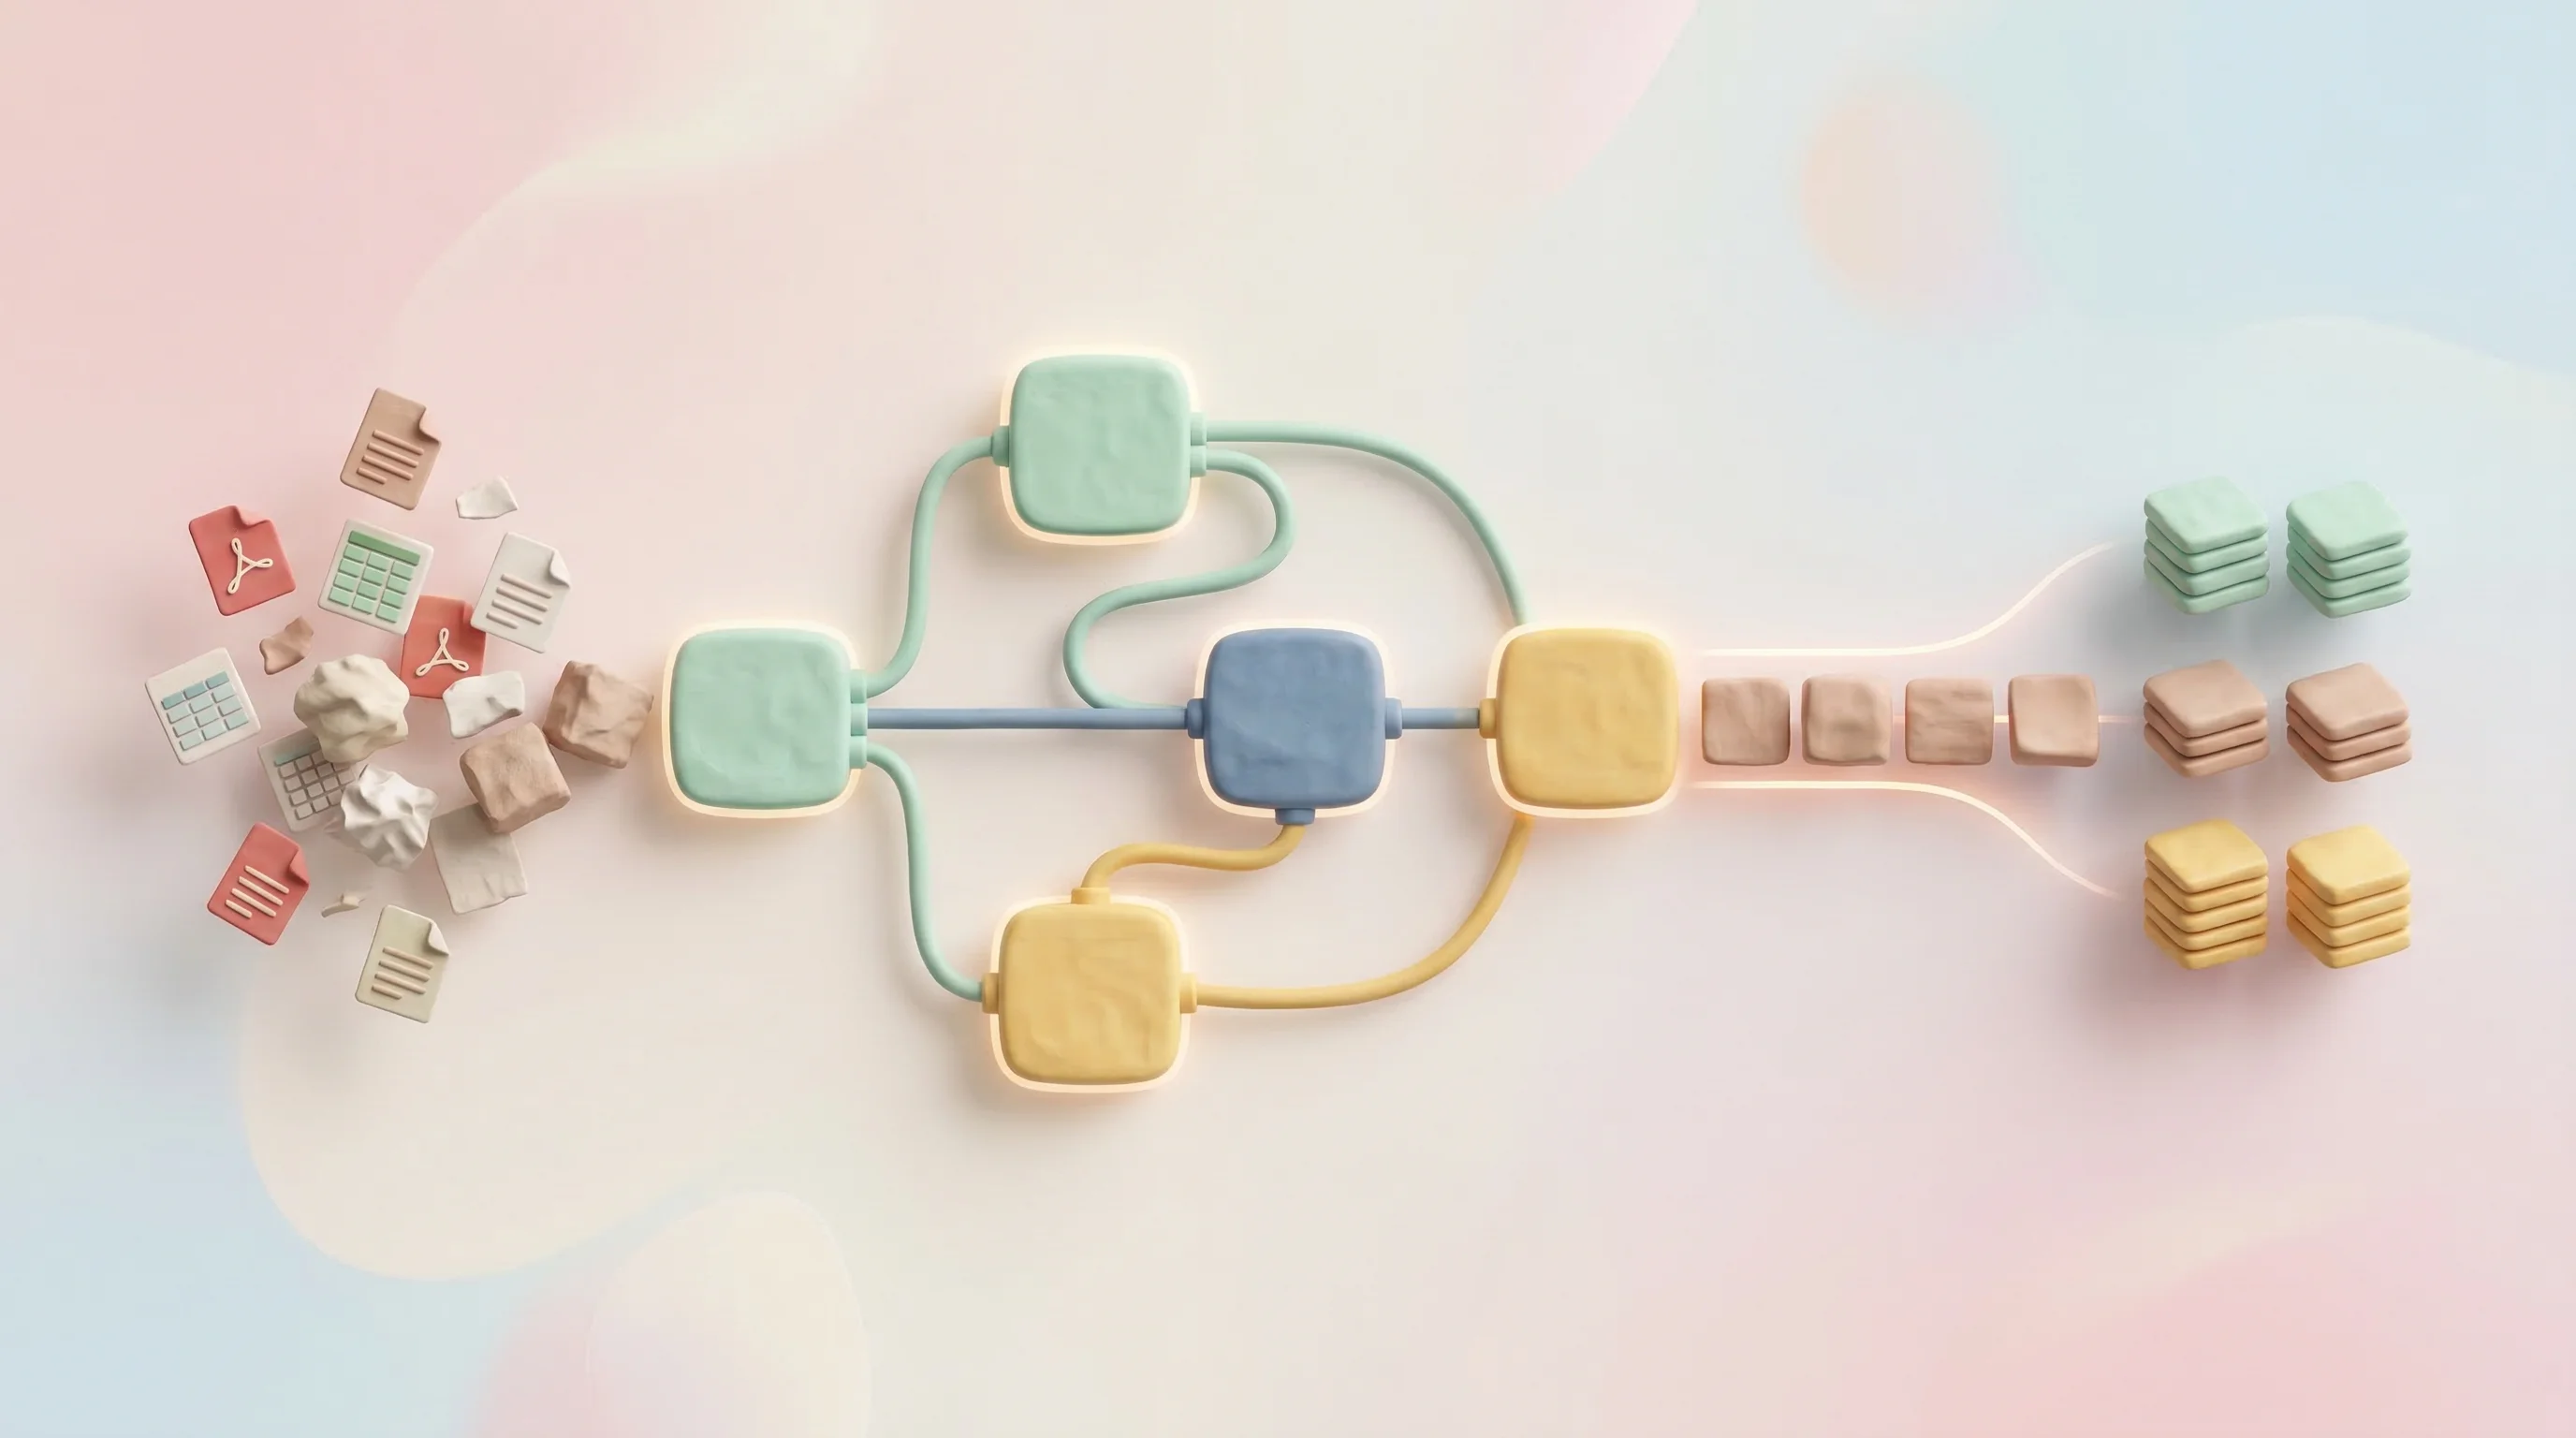
Where Studio diverges most sharply from competitors is Data Recipes—a visual node-graph system for transforming PDFs, spreadsheets, JSON dumps, and other messy formats into clean training datasets. It's powered by NVIDIA's NeMo Data Designer, a partnership thread that runs throughout Studio's technical foundation.
Anyone who's burned a Saturday writing preprocessing scripts knows the appeal. Whether the visual approach holds up under production-scale workloads is another matter, but it targets a genuine pain point. Not every developer wants to wrangle pandas DataFrames at 2 a.m.
NVIDIA's Shadow (and Spotlight)
NVIDIA's involvement extends well beyond Data Recipes. The chipmaker published technical documentation detailing Unsloth's performance on Blackwell GPUs and RTX 50 series cards. NVIDIA maintains installation guides for Unsloth on its DGX Spark platform. When Studio launched, the acknowledgements section thanked NVIDIA "for being part of our launch." A tutorial video from NVIDIA appeared shortly after.
The relationship makes strategic sense, perhaps more than the founders expected. Unsloth's optimization kernels—LoRA, FP8, and other training techniques—squeeze efficiency from NVIDIA hardware. Those performance gains matter considerably more when you're training on a $1,500 GPU in your office rather than renting time on cloud clusters.
Currently, training requires NVIDIA GPUs, though chat mode limps along on CPU-only setups. Support for Apple Silicon via MLX is listed as "coming very soon" based on recent team responses, with AMD and Intel somewhere further down the roadmap. The GPU dependency is both the product's strength and its Achilles' heel.
Existing Neighbors
Studio walks into a market already carved up by established tools serving different constituencies. LM Studio has claimed the local inference space with a polished desktop app and integrated model hub. LLaMA-Factory has become the default open-source training toolkit for teams comfortable with YAML configuration. Axolotl handles CLI-driven workflows for cloud and high-performance computing environments.
Community discussions wasted little time positioning Studio against these alternatives. One Reddit thread on launch day asked bluntly whether Unsloth was competing with LM Studio. The answer appears to be "partially"—Studio overlaps on inference but pivots on integrated training, particularly the no-code proposition.
LM Studio focuses on running models. LLaMA-Factory assumes you're fluent in configuration files. Studio attempts to collapse both use cases into a single interface optimized for hardware you already own. Whether that's elegant or just trying to do too much depends on who you ask.
Licensing Wrinkles
The project maintains what might charitably be called a "nuanced" license structure. Unsloth's core training libraries remain Apache 2.0—permissive and business-friendly. The Studio UI and certain optional components use AGPL 3.0, which carries more restrictive terms. This split drew immediate scrutiny in launch threads, especially from developers comparing it to more permissive alternatives.
For anyone building commercial products, the AGPL requirement means the UI code carries different constraints than the underlying training engine. The team hasn't yet detailed precisely which components fall under which license beyond the general division. That ambiguity probably won't age well.
Momentum Indicators
Unsloth didn't arrive at the Studio launch empty-handed. The company has stated that over 100,000 models trained with Unsloth have been open-sourced on Hugging Face, a number mentioned in community discussions. The GitHub repository reportedly crossed 50,000 stars in January, according to posts from contributors.
Studio's beta announcement rippled across multiple Reddit communities between mid-to-late March—r/LocalLLM, r/LocalLLaMA, r/selfhosted, r/unsloth. Product Hunt featured the launch days later. Early threads show the typical mix of enthusiasm and beta-grade friction: out-of-memory bugs in the model selector, questions about LoRA versus full fine-tuning capabilities.
Installation requires compiling llama.cpp on first run, adding 5-10 minutes to setup. The team plans precompiled binaries and maintains an official Docker image. A free Colab notebook exists for testing, though T4 GPUs compile more slowly than local hardware—a minor irony for a product positioning itself as local-first.
The Roadmap Ahead
Several features appeared marked "as soon as this week" in mid-March documentation, which in startup time might mean anything. OpenAI-compatible APIs for inference top that list. Multi-GPU support functions but a "major upgrade" is planned. macOS training via MLX is the most frequently requested addition in community threads, which makes sense given the installed base of M-series MacBooks among developers.
The company raised a seed round on October 7, 2024, though the amount hasn't been publicly disclosed. Investors include Y Combinator, Pioneer Fund, and several notable angels—Logan Kilpatrick from Google AI, Canva co-founder Cliff Obrecht, and Shutterstock founder Jon Oringer. Not a bad Rolodex for a team that went through Y Combinator's Summer 2024 batch.
Founders Daniel Han and Michael Han bring relevant pedigree. Daniel Han's background includes time at NVIDIA working on optimization, which shows in Unsloth's performance-oriented positioning. Whether that translates to sustainable competitive advantage is a longer conversation.
The Local Hypothesis
Studio's underlying thesis is that developers increasingly want to train models on their own hardware—whether for privacy, cost control, compliance, or simply the convenience of not debugging across a VPN at midnight. The 100% offline capability matters to teams handling sensitive data or operating in regulated industries where cloud services raise questions.
Whether that hypothesis holds depends partly on how training requirements evolve. Models keep expanding, but so do optimization techniques and specialized hardware. Unsloth is betting that the combination of efficient kernels, no-code workflows, and local execution creates enough value to pull training work out of AWS and GCP.
The beta label is entirely appropriate. Features are shipping incrementally, platform support remains incomplete, and the community is still shaking out edge cases. But the foundation—performance-optimized local training with a visual interface and NVIDIA's implicit endorsement—addresses real needs in the developer community.
How far Unsloth can push that advantage will depend on execution over the coming months as Studio matures. The competition isn't sleeping, and the market has a way of rewarding tools that solve one problem exceptionally well over those that try to solve many problems adequately. For now, Studio represents a bet that local training is ready to graduate from the command line to something closer to a consumer product.
It's a bet worth watching.


